Dedicated GPU infrastructure / US-based

Private AI infrastructure.Dedicated to your workload.

Run dedicated GPU infrastructure your way—from direct bare-metal access, to managed deployment environments, to private OpenAI-compatible inference.

From $799 / monthInstalled local NVMe includedUnmetered bandwidth
XM / DEDICATED SYSTEMS01 — 04
32—192 GB GPU MEMORY
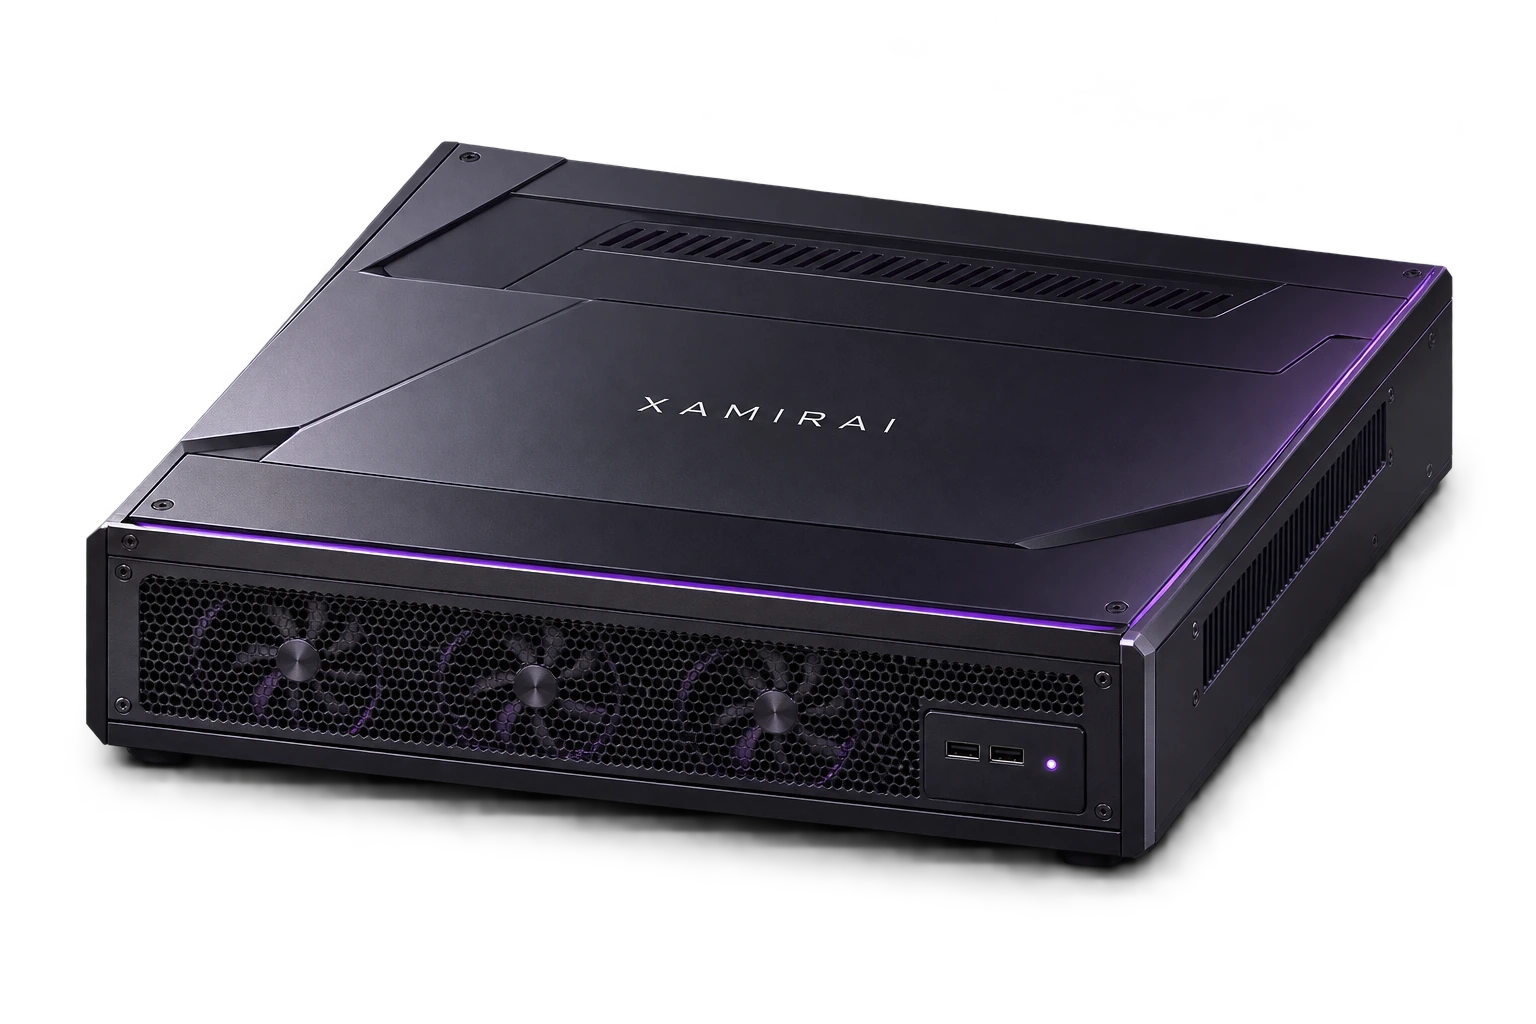
ONE PHYSICAL NODE. ENTIRELY YOURS.CONCEPT RENDER
EXPLORE THE SYSTEM

Instead of renting GPU-hours,
rent the AI server.

One physical node. One customer. One predictable monthly price. Choose how much of the infrastructure Xamirai manages while your capacity and environment stay reserved.

Start with the machine.
Add management as needed.

XAMIRAI PHYSICAL INFRASTRUCTURE→METAL→DEPLOY→INFERENCE
01 /XAMIRAI METAL

YOU MANAGE THE SOFTWARE

The machine is yours.

Dedicated bare-metal GPU infrastructure with root access and direct control of the operating system, runtime, and software stack.

  • Entire physical node
  • Root access + SSH
  • IPKVM / out-of-band access
  • Remote hands + hardware maintenance
02 /XAMIRAI DEPLOY

WE MANAGE THE ENVIRONMENT

Infrastructure without infrastructure management.

Everything in Metal, plus a Xamirai-managed deployment environment for containers, templates, networking, TLS, and persistent workloads.

  • Xamirai deployment portal
  • Docker + custom templates
  • Persistent environments
  • CUDA + driver management
03 /XAMIRAI INFERENCE

WE MANAGE EVERYTHING

Your model. Your hardware. Your private API.

Everything in Deploy, plus model serving and optimization behind an authenticated, OpenAI-compatible endpoint—with no per-token billing.

  • Private OpenAI-compatible API
  • Model + runtime operation
  • Context + concurrency tuning
  • Reserved capacity, not tokens

Stop watching
the meter.

Persistent AI workloads deserve infrastructure economics that are understandable before the invoice arrives.

01

NO GPU-HOUR METER

Your dedicated node is reserved for you for the month.

02

NO LOCAL STORAGE METER

Installed local NVMe capacity is included.

03

NO BANDWIDTH METER

Unmetered bandwidth with no per-GB ingress or egress charges.

04

NO TOKEN METER

Managed inference is priced by dedicated capacity, not tokens.

No-token-meter pricing applies to Xamirai Inference. Installed local NVMe capacity varies by node configuration.

Start at 32 GB.
Scale to 192 GB.

Entry configurations begin with a single 32 GB RTX 5090. PRO 96 and PRO 192 serve persistent high-memory workloads. Every configuration is available as Metal, Deploy, or fully managed Inference.

  • 01 Entire dedicated physical node
  • 02 Installed local NVMe included
  • 03 Unmetered bandwidth
  • 04 Persistent environment
  • 05 Direct technical support
View all configurations →
ENTRY / SINGLE GPU32 GB
FROM $799 / MONTH5090
GPU1× RTX 5090
Memory32 GB GPU memory
Best fitPrototyping + smaller-model inference
ENTRY / DUAL GPU64 GB
CONFIGURATION-BASED5090 DUO
GPU2× RTX 5090
Memory64 GB aggregate GPU memory
Best fitMulti-GPU inference + parallel workloads
FLAGSHIP / SINGLE GPU96 GB
CONFIGURATION-BASEDPRO 96
GPU1× RTX PRO 6000 Blackwell
Memory96 GB ECC GPU memory
Best fitHigh-memory single-GPU workloads
FLAGSHIP / DUAL GPU192 GB
CONFIGURATION-BASEDPRO 192
GPU2× RTX PRO 6000 Blackwell
Memory192 GB aggregate GPU memory
Best fitLarge + extended-context models

Your deployment is not a seat in a shared queue.

01CONTROLEntire physical hardware reserved for your workload.

02PERSISTENCEYour environment and local data stay put.

03PREDICTABILITYKnown monthly cost without GPU-hour or bandwidth metering.

04PRIVACY + ISOLATIONNo shared GPU and no noisy neighbors.

Reserve your node.
Lower your monthly cost.

Discounts are available for longer-term commitments. Billing remains monthly while the node is reserved for the agreed term.

LONGER-TERM COMMITMENTSDISCOUNTS AVAILABLE
PRICING APPROACHDEDICATED CAPACITY
ENTRY CONFIGURATIONFROM $799/mo
Full pricing details →

Keep the workload running.
Keep the environment yours.

01Private LLM inference
02RAG + document intelligence
03Fine-tuning
04AI research + development
05Image + video generation
06Long-running jobs
07Model evaluation
08Persistent development environments

Dedicated infrastructure,
with a defined operating model.

Xamirai currently operates single-site dedicated infrastructure with proactive monitoring and direct technical support. Services do not currently include multi-region redundancy or generator-backed availability.

Ready to size a node for your workload?

We can benchmark your model or workflow and recommend the right hardware and management layer.

Workload reviewNode recommendationManagement layerReserved-capacity proposal
Talk to Xamirai